High-Performance Data Solutions for AWS & Databricks

Accelerate your data platform with high-performance, cost-optimized solutions. We helped create the deltalake Python and Rust packages. we specialize in Delta Lake LTS, AWS Lambda optimizations, and turnkey data ingestion solutions.

Unlock 3-5x faster data pipelines with 40-60% lower costs

Contact us

Delta Lake Support

As creators of the deltalake Python and Rust packages, we have been supporting Delta Lake applications since the beginning. Buoyant Data offers one-time on-demand support as well as on-going technical support subscriptions for your team!

Rust Development

With years of experience creating and deploying Rust data applications with delta-rs, kafka-delta-ingest, and more, Buoyant Data can help your organization adopt and excel with high-performance, low-cost data services or AWS Lambdas built with Rust.

Data Architecture Consulting

Our expertise in leveraging Delta Lake includes both the Databricks Platform (Serverless, Unity, etc) and the AWS Data Platform (Glue, Athena, EMR). We can help design and implement a scalable and efficient data platform for your organization.

Infrastructure Optimization

For organizations with existing data infrastructure and analytics, we can analyze and optimize in-place to squeeze faster queries and lower costs out of your existing data platform without substantial rearchitecture.

Our Solutions

Delta Lake LTS

Enterprise-grade long-term support for Delta Lake with security patches and performance improvements backported.

Learn More

AWS Lambda Optimized

Lightning-fast data processing with our AWS Lambda distribution - 3x faster execution, 60% lower costs.

Learn More

Serverless Data Pipelines

Turnkey solutions for Kinesis, SQS, and Airbyte data ingestion into Delta Lake.

Explore Solutions

Introducing

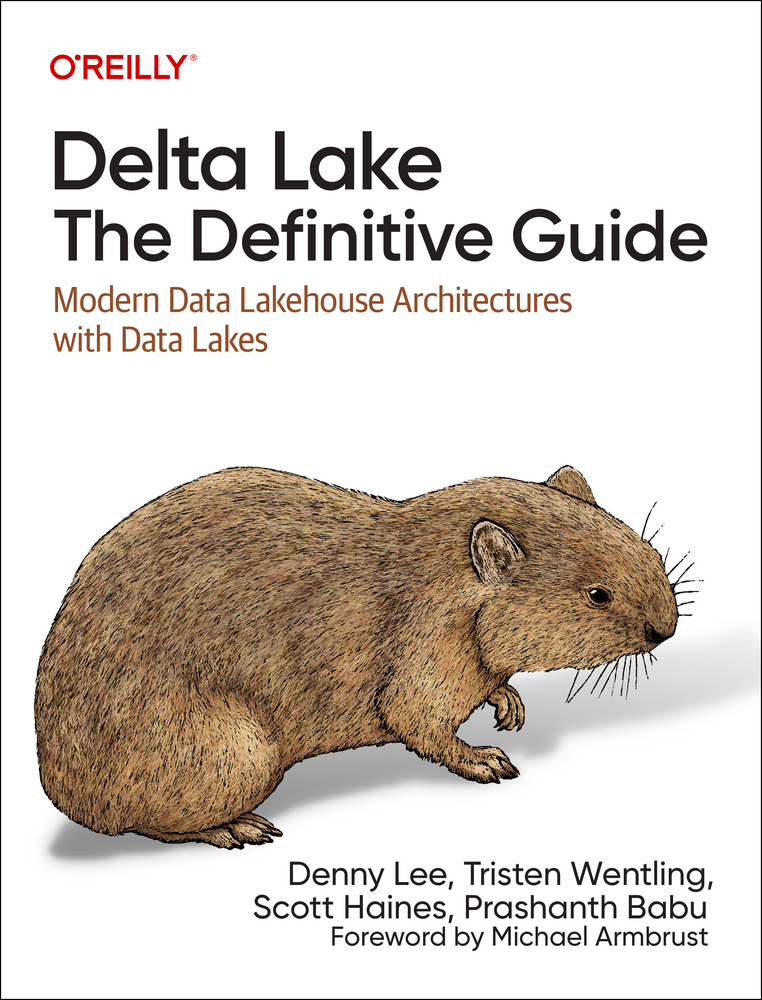
Delta Lake: The Definitive Guide

Expert insights on all things Delta Lake--including how to run batch and streaming jobs concurrently and accelerate the usability of your data. You'll also uncover how ACID transactions bring reliability to data lakehouses at scale.

Recent Posts

Crossing the workspaces with OpenSharing

Dive into the pattern of using OpenSharing to easily map read-only tables between Databricks workspaces, within one account or across accounts, without copying data and without exposing your catalogs to every workspace.

Is your Databricks platform on the right cloud?

Announcing our Azure to AWS migration services: lower infrastructure costs with Spot and Graviton compute, cheaper AI inference through Amazon Bedrock, and access to the best-in-class data tools on AWS, without disrupting the teams that depend on Databricks every day.

deltalake 1.0 is finally here!

deltalake 1.0.0 has shipped with support for deletion vectors, column-mapping, Spark-compatible CDF streaming, and buoyant_kernel 0.28 for faster fixes and improved snapshot metrics.